MLOps Pipeline for Agricultural Yield Prediction
Role: MLOps / Cloud Architect
Client: An AI/ML software company
The Challenge
The client needed an automated MLOps architecture on AWS to forecast crop yield and demand from seasonal, soil, fertilizer, and weather data. The system also had to recommend the optimal crops to plant per area and season to maximize yield.
The Solution
- Designed an event-driven, serverless MLOps pipeline that runs fully automated from ingestion to inference
- Used Amazon SageMaker for model training, hyperparameter tuning, and both batch and real-time inference endpoints
- Orchestrated the pipeline with AWS Step Functions, embedding model-validation logic between stages
- Built an S3 data lake backed by an RDS/DynamoDB feature and metadata store
- Handled data extraction, validation, and preparation with AWS Glue and ECS/Fargate jobs
- Wired AWS Lambda triggers for automated retraining and CloudWatch for continuous model-performance monitoring
Key Outcomes
Technologies Used
Project Overview
The client is an AI/ML software company building an agriculture-focused predictive analytics tool for one of their own customers. The goal was ambitious but concrete: forecast crop yield and demand well ahead of a growing season, then use those forecasts to recommend which crops a given area should plant to hit maximum yield.
The prediction problem itself was tractable — the harder part was operational. The models had to be trained, tuned, validated, deployed, and retrained continuously as new seasonal data arrived, without a team babysitting the process. I came in as the MLOps and cloud architect to design and build that automated backbone on AWS.
Business Challenge
Agricultural forecasting is only useful if it stays current. Soil conditions shift, fertilizer distribution changes area to area, and weather forecasts move constantly. A model trained once and left alone would drift out of usefulness within a season.
The client needed an architecture that could:
- Predict yield from collective signals — previous seasons’ data, fertilizers distributed in an area, soil type, and weather forecasts
- Recommend the best crops for specific areas based on yield possibility and market demand and supply
- Do all of this on an automated cadence, retraining as fresh data landed rather than on a human’s schedule
They had the domain models in mind. What they didn’t have was the automated MLOps and cloud architecture to run those models reliably and affordably.
Solution: Automated MLOps Architecture
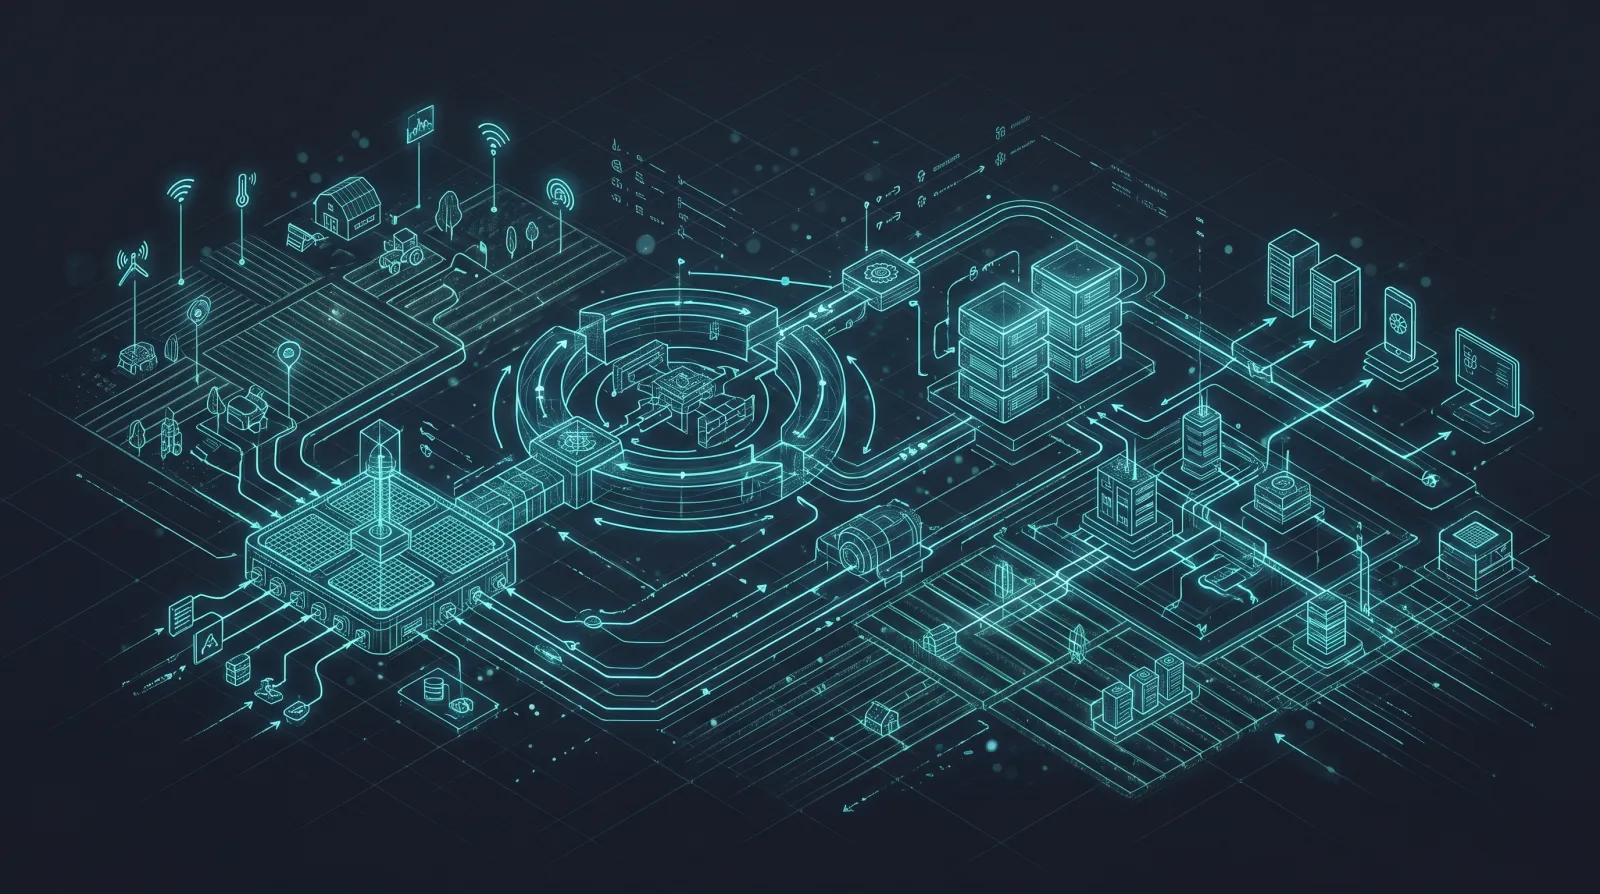
I proposed a serverless, event-driven pipeline. Serverless kept costs down and deployment simple, and the event-driven design meant the pipeline reacted to new data instead of waiting on a cron job or an engineer. Every stage — ingestion, preparation, training, validation, deployment, monitoring — was automated and stitched together as one flow.
Data Ingestion & Storage
Data arrives from multiple sources: historical yield records, fertilizer distribution data, soil profiles, and weather forecasts. I landed all of it in an Amazon S3 data lake, which also held flat-file extracts, source code, model artifacts, inference output, and metadata.
For structured features and metadata, I used a relational store on Amazon RDS, with DynamoDB for metadata on the use cases that needed fast key-value access. That split kept the feature store queryable while keeping pipeline metadata cheap and fast to read.
Model Training & Tuning (SageMaker)
Amazon SageMaker did the heavy lifting. It gave the pipeline a fully managed path to build, train, tune, and deploy models without provisioning training infrastructure by hand.
- Training jobs ran against prepared datasets pulled from S3
- Hyperparameter tuning jobs searched for the best-performing configurations automatically
- Inference was exposed two ways — batch transform for bulk seasonal forecasts and real-time endpoints for on-demand queries
Because SageMaker managed the training and tuning lifecycle, the pipeline could kick off a full retrain-and-tune cycle as a single orchestrated step.
Pipeline Orchestration (Step Functions)
AWS Step Functions tied the stages together. Rather than gluing jobs with brittle scripts, I modeled the pipeline as a state machine — data prep, training, tuning, validation, deployment — with explicit transitions and error handling.
The important piece here was model-validation logic built into the orchestration. A newly trained model didn’t get promoted automatically; Step Functions pulled evaluation metrics and gated deployment on them. A model that didn’t clear the bar never reached an endpoint.
Automated Retraining
The pipeline retrained itself. AWS Lambda functions acted as triggers — when new data arrived or conditions warranted a refresh, Lambda kicked off the Step Functions workflow to prepare data and start a new SageMaker training run.
Data extraction, validation, and preparation ahead of each training job ran on AWS Glue and ECS/Fargate, depending on the shape and volume of the work. This is what made the system genuinely hands-off: fresh seasonal data flowed in, and updated models flowed out, without anyone starting the process manually.
Monitoring
Amazon CloudWatch watched the SageMaker training and tuning jobs and the pipeline as a whole. Combined with Step Functions retrieving evaluation metrics inside the pipeline, this gave the client continuous visibility into model performance — not just whether jobs ran, but whether the models coming out the other side were any good.
Outcomes
The delivered system was automated end to end and produced the seasonal forecasts the client needed:
- Total crop yields expected during a season
- Yield possibility for individual crops
- Maximum and minimum yielding crops for planning
- Best crops for specific areas and seasons
Beyond the forecasts themselves, the architecture delivered the operational properties that made it worth building:
- Fully automated retraining driven by new data, with no manual triggering
- Continuous performance monitoring through CloudWatch and Step Functions evaluation metrics
- Serverless cost efficiency — the pipeline only consumed resources when there was work to do
Key Learnings
- The model is the easy part; the pipeline around it is the product. The client already knew what to predict. The value I added was making those predictions reproducible, current, and cheap to run.
- Gate deployment on validation, always. Building model-validation logic into Step Functions meant a bad training run could never quietly ship to production. Automation without gates just automates mistakes.
- Event-driven beats scheduled for data that moves. Agricultural inputs change on their own timeline, not a cron schedule. Letting Lambda trigger retraining on new data kept the models aligned with reality.
- Serverless is a good default for spiky ML workloads. Training and forecasting happen in bursts, not continuously. Scaling to zero between runs kept the economics sane without sacrificing responsiveness.
Interested in similar results?
Let's discuss how I can help your organization achieve its goals.
Get in Touch