GenAI Claims Automation Platform for an InsurTech
Role: Cloud Solutions Architect
Client: An insurance claims platform
The Challenge
An insurance claims platform was drowning in slow, manual claim processing — long turnaround times, high operational cost, inconsistent decisions, and limited fraud detection. They needed to transition to an automated, scalable GenAI workflow without sacrificing compliance or explainability.
The Solution
- Designed an event-driven claims pipeline on ECS Fargate handling submission, analysis, routing, and decisioning end to end
- Automated document intake with Amazon Textract for OCR extraction and Amazon Comprehend for PII redaction and privacy compliance
- Built GenAI document verification on Amazon Bedrock (GPT-OSS-120B) with structured prompt engineering to gate claim submission on authentic, relevant documents
- Deployed a custom SageMaker fraud-scoring model behind real-time inference endpoints, with Lambda feature preprocessing for sub-second scoring
- Implemented safe model rollout using canary traffic shifting (blue/green fleets) with automated rollback on error thresholds
- Embedded responsible-AI governance, audit logging, and monitoring into the lifecycle from day one
Key Outcomes
Technologies Used
Project Overview
The client is an insurance claims platform betting on Generative AI to reinvent how claims move from submission to decision. Their goal was ambitious but concrete: automate document processing, fraud detection, and validation across the claims lifecycle, and do it under a governance model they could defend to regulators.
I came in as Cloud Solutions Architect to design and stand up the GenAI operating model on AWS — the orchestration layer, the document-understanding pipeline, the GenAI verification gate, and a custom fraud-detection model with a deployment strategy safe enough to run in production.
The Challenge
Before adopting GenAI, the platform hit a familiar wall for a fast-growing InsurTech:
- Slow claim processing meant long turnaround times and unhappy customers
- Operational costs were high and workflows were hard to scale
- Manual, inconsistent decision-making drove up error rates
- Compliance and security demands kept rising across claims operations
- Available data was underused — fraud detection was weak
The real problem wasn’t any single bottleneck. It was the absence of an automated, scalable, governed pipeline that could hold consistency and compliance while moving fast.
Solution / Architecture
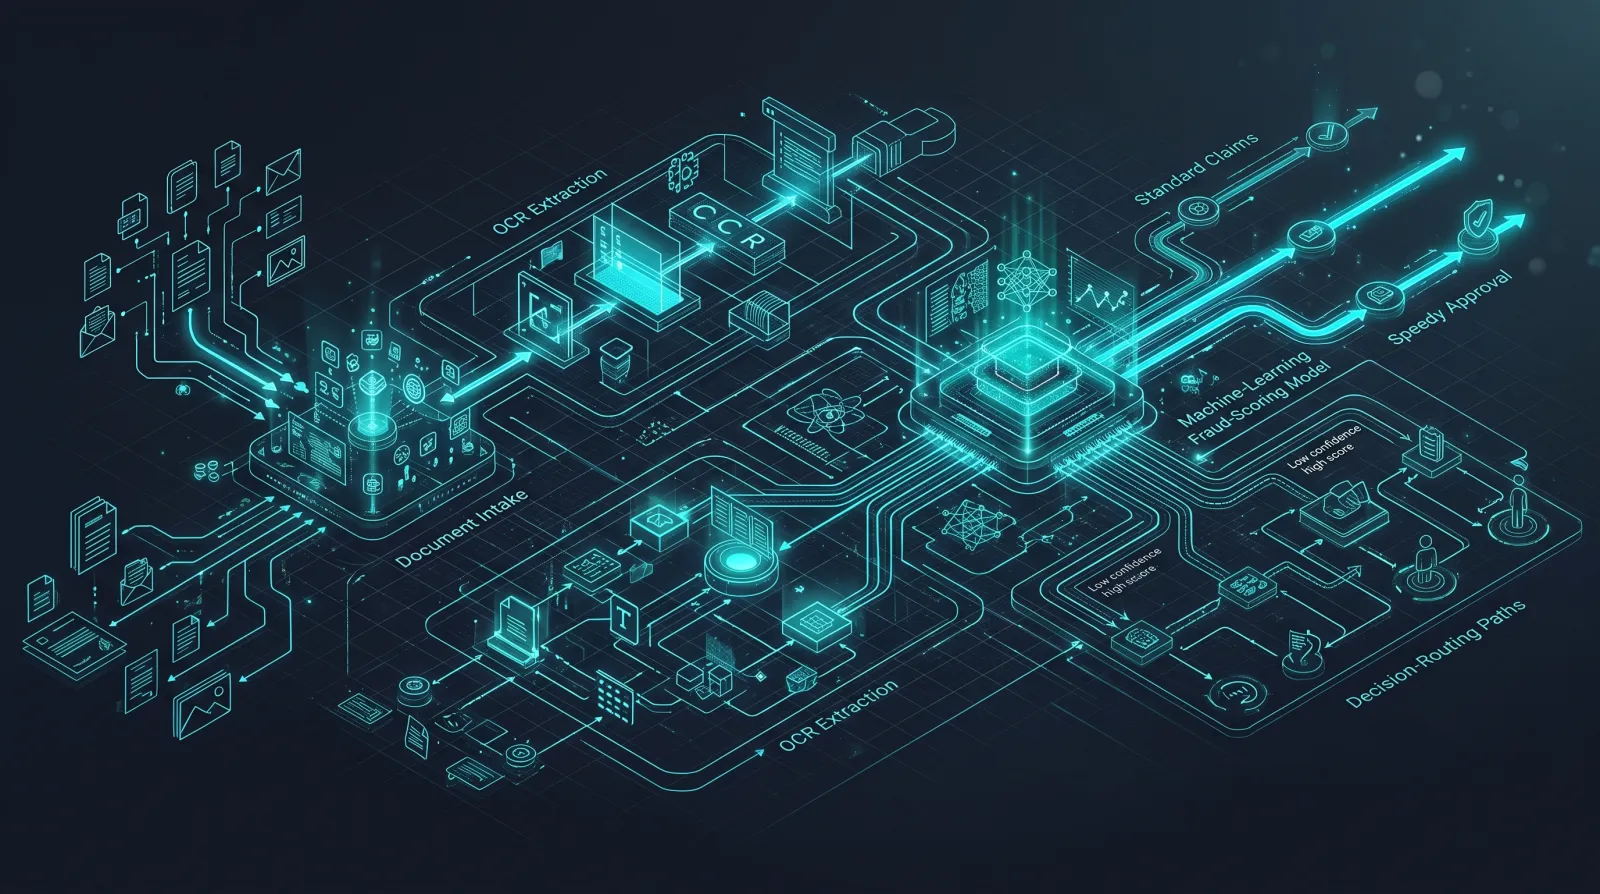
I built a consulting-led GenAI operating model on AWS — governed capabilities wired into an automated claims workflow, with model selection, prompt engineering, and lifecycle governance treated as first-class concerns.
Orchestration on ECS Fargate
Containerized services on ECS Fargate manage the full claim workflow: submission, analysis, routing, and decisioning. Fargate kept the orchestration layer serverless from an operations standpoint — no node fleet to babysit — while still giving me the control I needed over the long-running claim state machine.
Document Understanding
Every claim starts with documents, so document quality gates everything downstream:
- Amazon Textract extracts text and structured data from uploaded claim documents via OCR
- Amazon Comprehend redacts PII before data moves further, keeping the pipeline compliant with privacy requirements
GenAI Verification Gate
Amazon Bedrock, running the GPT-OSS-120B model, verifies whether an uploaded document is relevant and authentic before a claim can be submitted. Structured prompt engineering keeps the evaluation consistent and policy-aligned — the same document produces the same judgment, and the reasoning stays explainable. The client cannot submit the form unless a valid document clears this gate. That single control removed a huge class of downstream noise and rework.
Custom Fraud Detection
Once a claim form is submitted, its features are sent to a Lambda function that preprocesses them and calls a custom fraud-detection model deployed on Amazon SageMaker. The model returns a real-time fraud probability score, and a post-processing step turns that into a final decision. Real-time inference endpoints keep scoring sub-second.
Safe Deployment Strategy
Shipping a new fraud model is risky — a bad model silently approves fraud or blocks good claims. I used SageMaker canary traffic shifting to make deployments boring:
- The new model launches as a green fleet; the existing model stays as the blue fleet
- 30% of traffic routes to green, 70% stays on blue during a 10-minute observation window
- If alarms trigger (for example HTTP 5XX errors), SageMaker automatically rolls back to blue
- If clean, traffic shifts fully to green, the blue fleet is terminated, and the rollout completes
Data & Governance
Amazon RDS (PostgreSQL) stores claims data, model artifacts, and audit logs. Responsible-AI practices, monitoring, and audit trails were embedded from the start rather than bolted on — which is what let the platform defend the system’s decisions rather than just trust them.
Results
- Over 80% reduction in claims lifecycle time. Automated document handling and fraud checks compressed resolution dramatically.
- Stronger, faster fraud detection. The Bedrock verification gate plus the custom SageMaker model caught fraudulent claims more accurately and earlier in the flow.
- More reliable, transparent AI operations. Custom models improved fraud accuracy while raising decision transparency, reliability, and governance.
- Predictable economics. A one-year TCO analysis put the ECS-based architecture at roughly $1,146/month (~$13,755/year), giving the client a defensible cost basis for the decision.
The broader business impact: faster resolution, better customer experience, reduced operational risk, and a sustainable foundation for continued GenAI work.
Key Learnings
- Strategy before models. Aligning GenAI capabilities with business objectives and risk frameworks mattered more than any single model choice.
- Model selection is a governance decision. The right model balances raw performance against regulatory compliance, ethics, and operational oversight — not just benchmark scores.
- Prompt engineering is infrastructure. Structured prompts and orchestration are what make GenAI reliable, scalable, and context-aware in production.
- Bake in responsible AI from day one. Governance frameworks added after the fact never fit; embedded from the start, they become the thing that lets you ship confidently.
- Make deployment boring. Canary shifting with automated rollback turned model releases from a nail-biting event into a routine one.
Interested in similar results?
Let's discuss how I can help your organization achieve its goals.
Get in Touch